
 Chrome に追加

Step 3.7 Flash is StepFun's multimodal vision-language model, built on Step 3.5 Flash with an added vision encoder for native image understanding. With a 256k context window, selectable reasoning levels, and high throughput, it targets agentic, coding, and search workflows that mix text and visual input.
コスト率
0.2x
コンテキスト
262K
リリース
2026年5月28日
入力
TextImageVideo
出力
Text
対応
推論ツール呼び出し構造化出力
パフォーマンス
最近のリクエストで測定したレイテンシとスループットの中央値。
スループット131 tok/s
レイテンシ2.8s
得意なこと
このモデルが最も高くランクされているカテゴリーです。
上位カテゴリーが見つかりませんでした。
| カテゴリ | 勝率 | 順位 |
|---|---|---|
| ASCII Art | 44.3% | #50 |
| Data Visualization | 43.2% | #73 |
| SVG | 36.3% | #76 |
| Website | 43.6% | #76 |
| Code Categories | 41.7% | #77 |
| UI Component | 41.2% | #78 |
| Game Development | 36.9% | #83 |
| 3D | 39.6% | #93 |
Step 3.7 Flashに関する最新ニュース
最近の記事やコミュニティの投稿を、元のソースへのリンク付きで表示します。
 Faux Triple Step Fun Fold - Mystery Stamping Revealed - 11-4-26Delight of my Art4,352
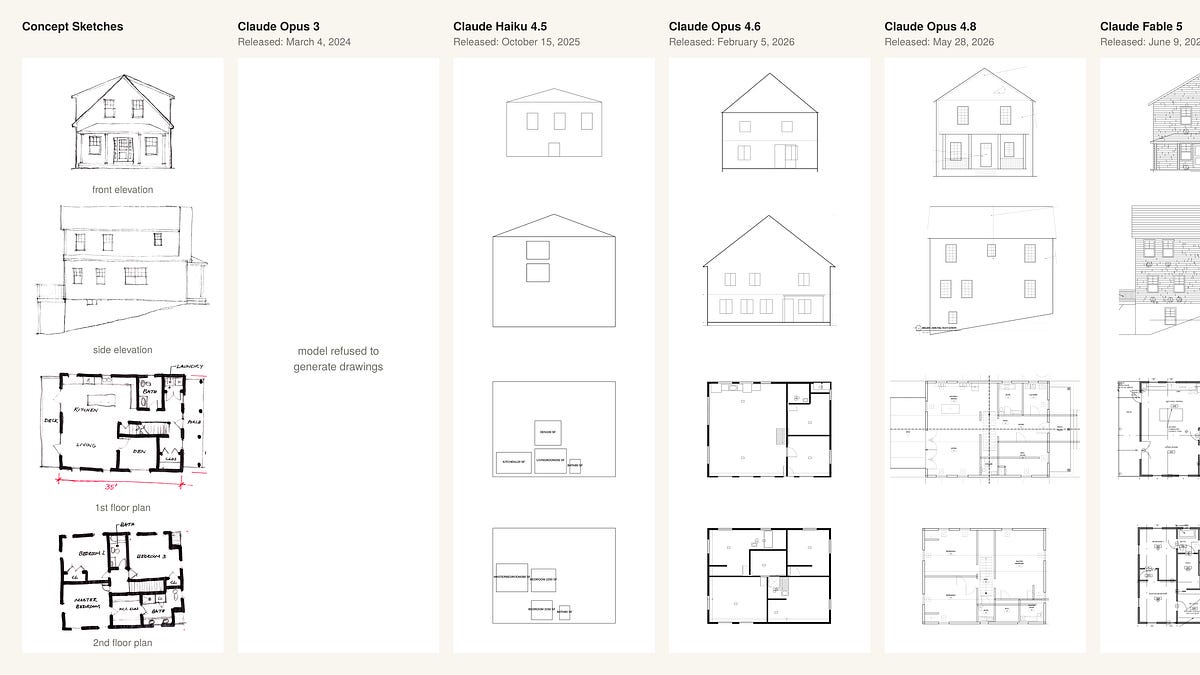 Claude Opus 5.5 Can Draw Permit-Level Architectural DrawingsHacker News10638

- Neal Stephenson on AI and What Comes Next [video]Hacker News5624
 How many shots are in the average movie today?Hacker News4516
- The Cost of Context: StepFun’s Cache-First EconomicsYahoo Finance