
 Chrome에 추가

Step 3.7 Flash is StepFun's multimodal vision-language model, built on Step 3.5 Flash with an added vision encoder for native image understanding. With a 256k context window, selectable reasoning levels, and high throughput, it targets agentic, coding, and search workflows that mix text and visual input.
비용 비율
0.2x
컨텍스트
262K
출시일
2026년 5월 28일
입력
TextImageVideo
출력
Text
지원
추론도구 호출구조화된 출력
성능
최근 요청 전반에서 측정한 중앙 지연 시간과 처리량입니다.
처리량131 tok/s
지연 시간2.8s
강점 분야
이 모델이 가장 높은 순위를 차지하는 카테고리입니다.
강점 카테고리를 찾을 수 없습니다.
| 카테고리 | 승률 | 순위 |
|---|---|---|
| ASCII Art | 44.3% | #50 |
| Data Visualization | 43.2% | #73 |
| SVG | 36.3% | #76 |
| Website | 43.6% | #76 |
| Code Categories | 41.7% | #77 |
| UI Component | 41.2% | #78 |
| Game Development | 36.9% | #83 |
| 3D | 39.6% | #93 |
Step 3.7 Flash 관련 최신 뉴스
최근 기사와 커뮤니티 게시물을 원문 출처 링크와 함께 확인하세요.
 Faux Triple Step Fun Fold - Mystery Stamping Revealed - 11-4-26Delight of my Art4,352
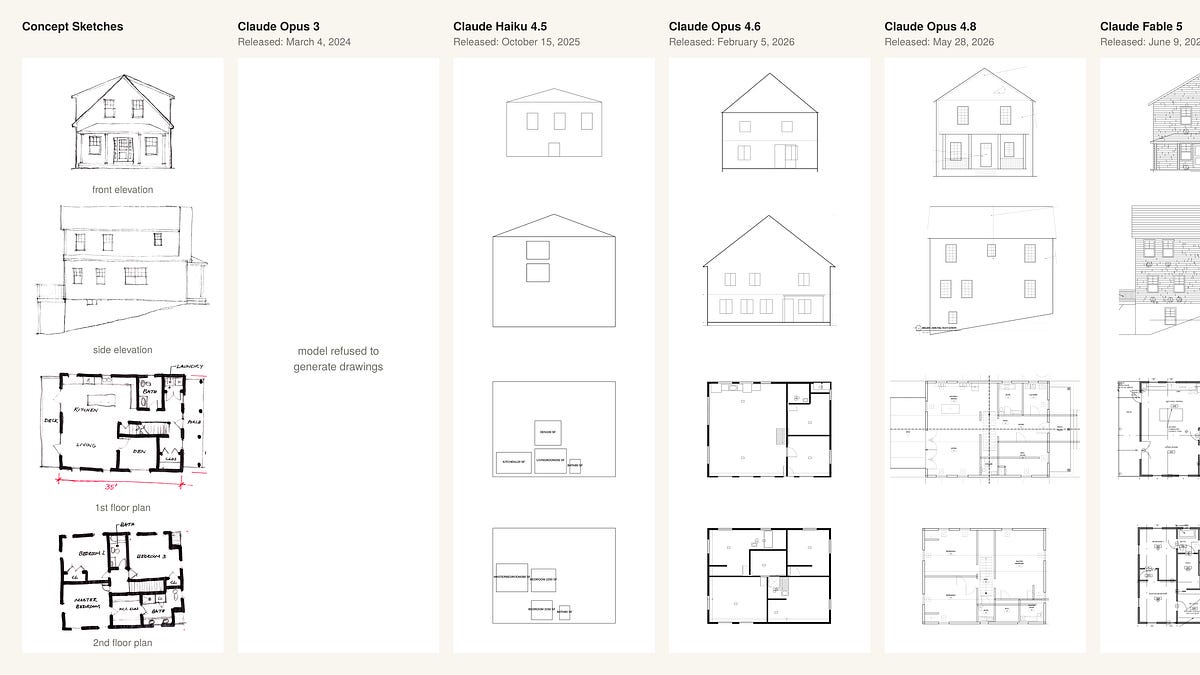 Claude Opus 5.5 Can Draw Permit-Level Architectural DrawingsHacker News10638

- Neal Stephenson on AI and What Comes Next [video]Hacker News5624
 How many shots are in the average movie today?Hacker News4516
- The Cost of Context: StepFun’s Cache-First EconomicsYahoo Finance