
 Aggiungi a Chrome

Step 3.7 Flash is StepFun's multimodal vision-language model, built on Step 3.5 Flash with an added vision encoder for native image understanding. With a 256k context window, selectable reasoning levels, and high throughput, it targets agentic, coding, and search workflows that mix text and visual input.
Fascia di costo
0.2x
Contesto
262K
Rilasciato
28 mag 2026
Input
TextImageVideo
Output
Text
Supporto
RagionamentoChiamata di strumentiOutput strutturati
Prestazioni
Latenza e velocità mediane misurate sulle richieste recenti.
Velocità131 tok/s
Latenza2.8s
In cosa eccelle
Le categorie in cui questo modello ottiene i risultati migliori.
Nessuna categoria con classifica elevata trovata.
| Categoria | Percentuale di vittorie | Posizione |
|---|---|---|
| ASCII Art | 44.3% | #50 |
| Data Visualization | 43.2% | #73 |
| SVG | 36.3% | #76 |
| Website | 43.6% | #76 |
| Code Categories | 41.7% | #77 |
| UI Component | 41.2% | #78 |
| Game Development | 36.9% | #83 |
| 3D | 39.6% | #93 |
Ultime notizie su Step 3.7 Flash
Articoli recenti e post della community, con link alle fonti originali.
 Faux Triple Step Fun Fold - Mystery Stamping Revealed - 11-4-26Delight of my Art4,352
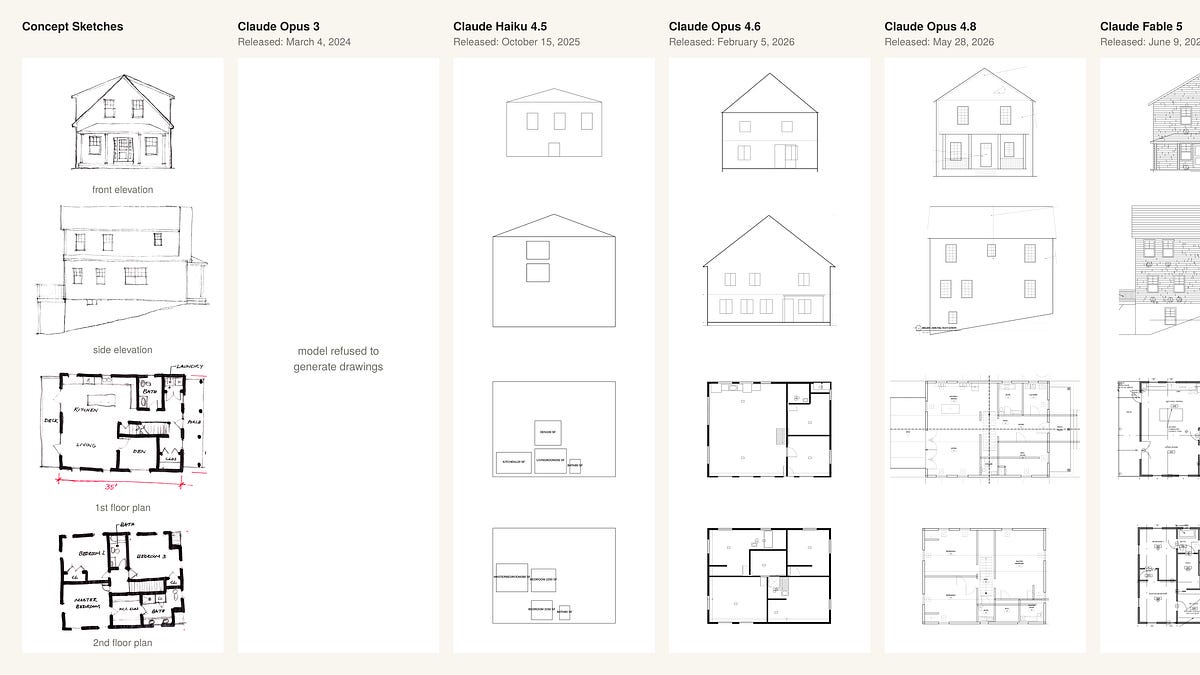 Claude Opus 5.5 Can Draw Permit-Level Architectural DrawingsHacker News10638

- Neal Stephenson on AI and What Comes Next [video]Hacker News5624
 How many shots are in the average movie today?Hacker News4516
- The Cost of Context: StepFun’s Cache-First EconomicsYahoo Finance