
 Adicionar ao Chrome

Step 3.7 Flash is StepFun's multimodal vision-language model, built on Step 3.5 Flash with an added vision encoder for native image understanding. With a 256k context window, selectable reasoning levels, and high throughput, it targets agentic, coding, and search workflows that mix text and visual input.
Taxa de custo
0.2x
Contexto
262K
Lançamento
28 de mai. de 2026
Entrada
TextImageVideo
Saída
Text
Suporte
RaciocínioChamada de ferramentasSaídas estruturadas
Desempenho
Latência e vazão medianas medidas em solicitações recentes.
Vazão142 tok/s
Latência2.68s
Melhor em
As categorias em que este modelo tem o melhor desempenho.
Nenhuma categoria de destaque encontrada.
| Categoria | Taxa de vitória | Classificação |
|---|---|---|
| ASCII Art | 44.3% | #48 |
| Data Visualization | 43.2% | #73 |
| Code Categories | 41.7% | #76 |
| SVG | 36.3% | #76 |
| Website | 43.7% | #76 |
| UI Component | 41.2% | #78 |
| Game Development | 37.0% | #83 |
| 3D | 39.6% | #93 |
Últimas notícias sobre Step 3.7 Flash
Artigos recentes e publicações da comunidade, com links para as fontes originais.
 Faux Triple Step Fun Fold - Mystery Stamping Revealed - 11-4-26Delight of my Art4,304
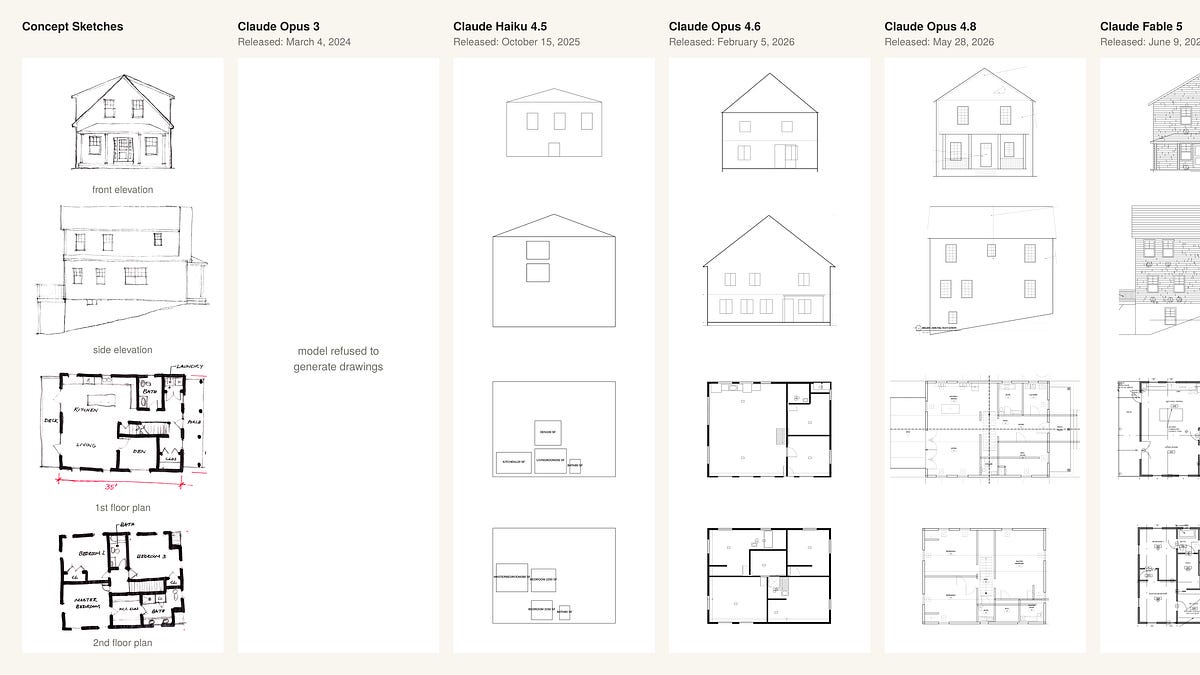 Claude Opus 5.5 Can Draw Permit-Level Architectural DrawingsHacker News10638
- Neal Stephenson on AI and What Comes Next [video]Hacker News5624
 Step 5 Preview vs Claude Opus 4.8 (Real Tests)Damian Malliaros8,286
 How many shots are in the average movie today?Hacker News4516