
 添加到 Chrome

Step 3.7 Flash is StepFun's multimodal vision-language model, built on Step 3.5 Flash with an added vision encoder for native image understanding. With a 256k context window, selectable reasoning levels, and high throughput, it targets agentic, coding, and search workflows that mix text and visual input.
费用比率
0.2x
上下文
262K
发布日期
2026年5月28日
输入
TextImageVideo
输出
Text
支持
推理工具调用结构化输出
性能
根据近期请求测得的中位延迟和吞吐量。
吞吐量142 tok/s
延迟2.68s
最擅长
该模型排名最高的类别。
未找到排名靠前的类别。
| 类别 | 胜率 | 排名 |
|---|---|---|
| ASCII Art | 44.3% | #48 |
| Data Visualization | 43.2% | #73 |
| Code Categories | 41.7% | #76 |
| SVG | 36.3% | #76 |
| Website | 43.7% | #76 |
| UI Component | 41.2% | #78 |
| Game Development | 37.0% | #83 |
| 3D | 39.6% | #93 |
关于 Step 3.7 Flash 的最新资讯
近期文章和社区帖子,均链接至原始来源。
 Faux Triple Step Fun Fold - Mystery Stamping Revealed - 11-4-26Delight of my Art4,304
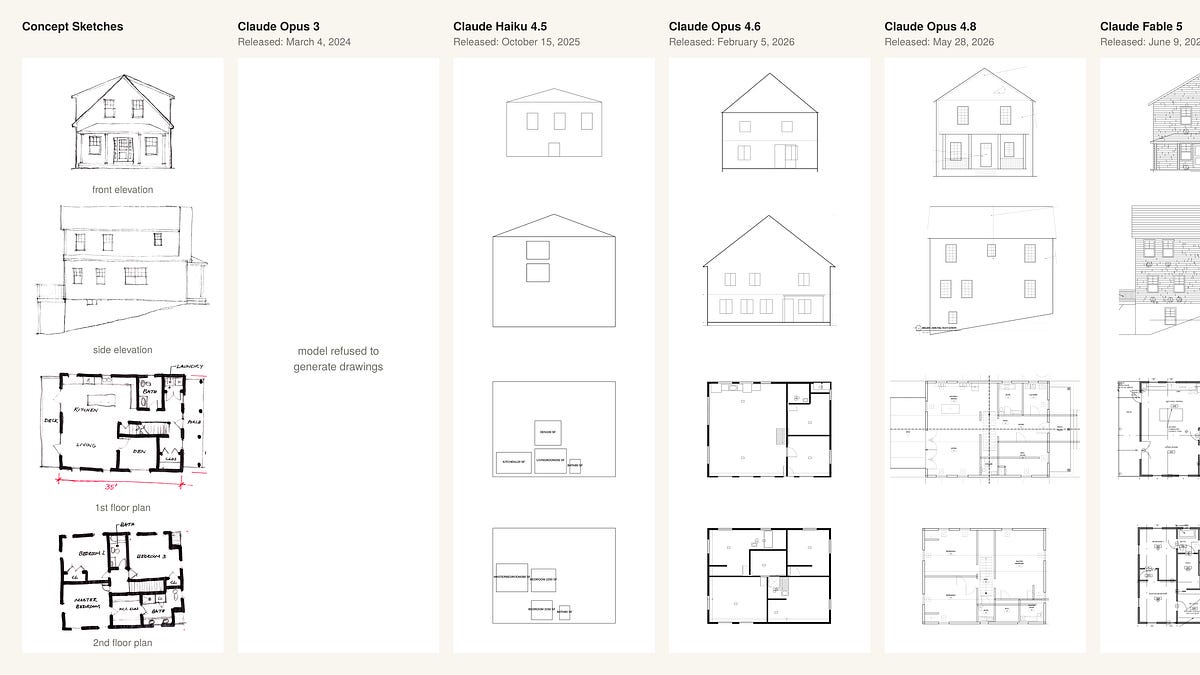 Claude Opus 5.5 Can Draw Permit-Level Architectural DrawingsHacker News10638
- Neal Stephenson on AI and What Comes Next [video]Hacker News5624
 Step 5 Preview vs Claude Opus 4.8 (Real Tests)Damian Malliaros8,286
 How many shots are in the average movie today?Hacker News4516