
 Add to Chrome

Step 3.7 Flash is StepFun's multimodal vision-language model, built on Step 3.5 Flash with an added vision encoder for native image understanding. With a 256k context window, selectable reasoning levels, and high throughput, it targets agentic, coding, and search workflows that mix text and visual input.
Cost rate
0.2x
Context
262K
Released
May 28, 2026
Input
TextImageVideo
Output
Text
Support
ReasoningTool callingStructured outputs
Performance
Median latency and throughput measured across recent requests.
Throughput142 tok/s
Latency2.68s
Best at
The categories where this model ranks highest.
No top-ranked categories found.
| Category | Win rate | Rank |
|---|---|---|
| ASCII Art | 44.3% | #48 |
| Data Visualization | 43.2% | #73 |
| Code Categories | 41.7% | #76 |
| SVG | 36.3% | #76 |
| Website | 43.7% | #76 |
| UI Component | 41.2% | #78 |
| Game Development | 37.0% | #83 |
| 3D | 39.6% | #93 |
Latest news about Step 3.7 Flash
Recent articles and community posts, linked to their original sources.
 Faux Triple Step Fun Fold - Mystery Stamping Revealed - 11-4-26Delight of my Art4,304
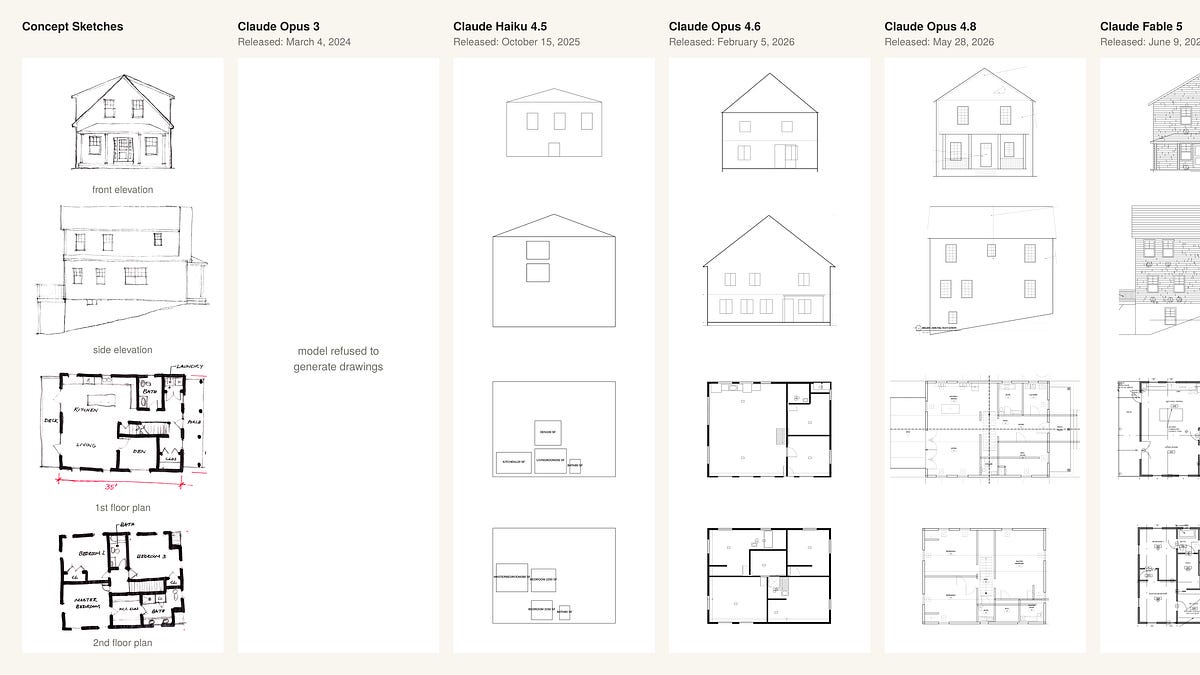 Claude Opus 5.5 Can Draw Permit-Level Architectural DrawingsHacker News10638
- Neal Stephenson on AI and What Comes Next [video]Hacker News5624
 Step 5 Preview vs Claude Opus 4.8 (Real Tests)Damian Malliaros8,286
 How many shots are in the average movie today?Hacker News4516